Insights & Essays.
Field notes for CTOs and principal engineers: what shipped, what failed, and how to staff the next AI program. Depth first — no vendor recap.
Latest Articles
GBS as Agentic AI Launchpad: Why Shared Services Win Transformation Before HQ Does
Discover why Global Business Services (GBS) outpaces corporate headquarters in agentic AI transformation.
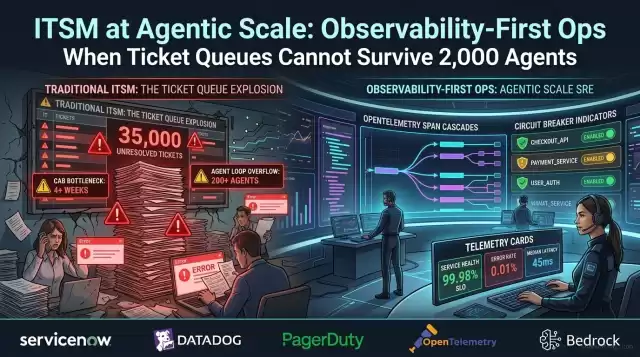
ITSM at Agentic Scale: Observability-First Ops When Ticket Queues Cannot Survive 2,000 Agents
Traditional IT service management drowns when 2,000+ autonomous agents deploy.
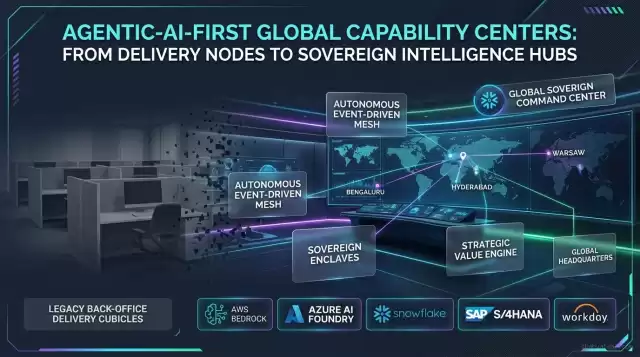
Agentic-AI-First Global Capability Centers: From Delivery Nodes to Sovereign Intelligence Hubs
EY's 2026 GCC thesis: next-generation Global Capability Centers are not merely digital-first—they are Agentic-AI-First by design.
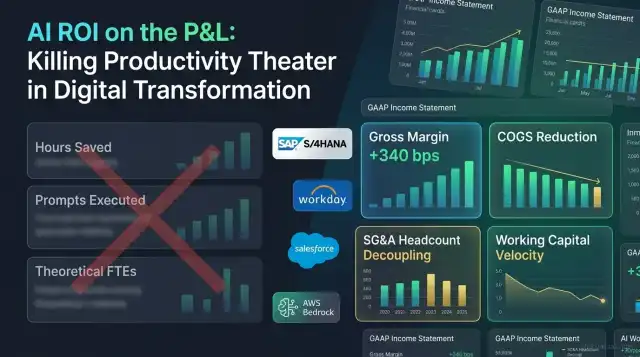
AI ROI on the P&L: Killing Productivity Theater in Digital Transformation
Why enterprise AI productivity dashboards are losing budget battles.
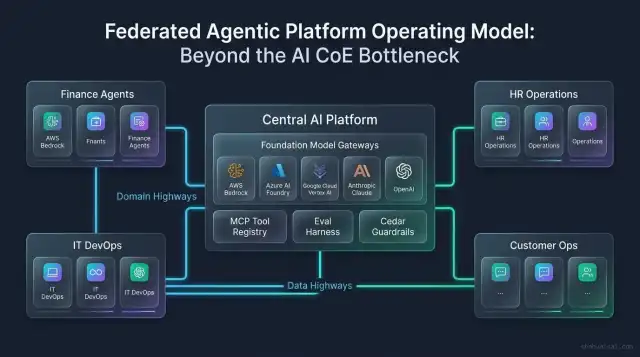
Federated Agentic Platform Operating Model: Killing the AI CoE That Blocks Enterprise Transformation
Why centralized AI Centers of Excellence (CoEs) bottleneck enterprise transformation.
OWASP Top 10 for Agentic AI (ASI01-ASI10): Implementation Guide for Enterprise Teams
Master OWASP's Top 10 for Agentic AI (ASI01-ASI10).
PLG 3.0: Agent-Led Growth and the Death of the Freemium Ceiling
Product-Led Growth (PLG) 3.0 shifts SaaS scaling to Agent-Led Growth (ALG).
Cursor Rules (.cursorrules) Engineering: Programming Agentic IDEs for Strict Architectural Compliance
Master .cursorrules and .cursor/rules/*.mdc files to enforce coding standards, security policies, and directory architecture on AI agents in Cursor IDE
LLM Evaluation in Production: Agent Benchmarks That Actually Predict Failure
Stop relying on MMLU or static evals. Build a production agentic evaluation pipeline with golden sets, CI/CD regression testing, and real-time shadow
External Standards & Publications
Our engineering publications follow industry standards for software architecture and agentic AI systems. Read more about technical specifications at the IEEE Standards Association and general web engineering principles at the World Wide Web Consortium (W3C).
What is “LLM Evaluation in Production” about?
Stop relying on MMLU or static evals. Build a production agentic evaluation pipeline with golden sets, CI/CD regression testing, and real-time shadow.
Who wrote this article and when was it published?
Written by Vatsal Shah, an AI Leader and Solution Architect based in Ahmedabad, India, and published on June 28, 2026. Reading time is 20 min read. It is filed under AI / MLOps.
How can I apply this in my own organization?
Use the sections of this article as a working checklist, adapt each step to your platform and risk profile, and record the decisions you make. To discuss LLM Evaluation in Production for your team, request a briefing at https://shahvatsal.com/contact.