Insights & Essays.
Field notes for CTOs and principal engineers: what shipped, what failed, and how to staff the next AI program. Depth first — no vendor recap.
Latest Articles
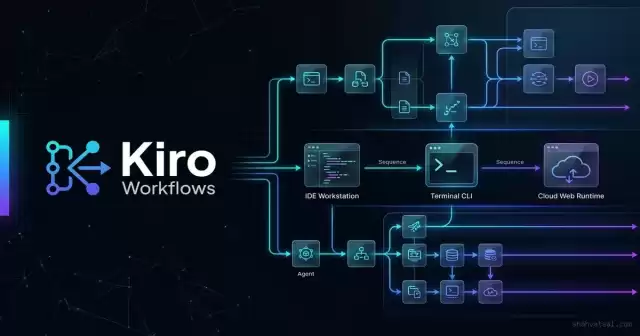
Kiro Workflows: Graphs of Agents, Not Another Spec File
A deep technical analysis of Kiro Workflows launched Sep 30, 2026. Explore multi-agent DAG execution, isolated fresh context per step, bundled recipes, and cross-platform runtime.
AG-UI 1.0: The Open Event Protocol That Connects Any AI Agent to Any Application Interface
An in-depth technical analysis of CopilotKit's AG-UI 1.0 protocol specification, JSON Schema event streams, multimodal tool results, and the MCP-A2A-AGUI triad.
Claude Cowork in Every Conversation: Unifying Quick Prompts, Deep Knowledge Work, and Artifacts Across One Thread
Anthropic unifies Claude Cowork into every conversational thread, eliminating mode pickers while bringing Claude Design, Slides, and Docs natively inside…
Google A2A Protocol: Building Vendor-Agnostic Multi-Agent Networks Beyond MCP in 2026
Master Google's Agent-to-Agent (A2A) protocol. Connect LangGraph, CrewAI, AutoGen, and Vertex AI across enterprise boundaries with verifiable credentials.
Vertical AI Agents: Domain-Specific Architecture for Healthcare, Legal, and Finance Autonomy in 2026
Vertical AI agents achieve 87%+ task completion vs 55% for general agents.
Mastering CLAUDE.md, AGENTS.md, and SKILL.md: Anthropic's 7-Method Steering System for Claude Code
Learn Anthropic's definitive 7-method steering system for Claude Code.
Claude Coworker in Production: Architecting Collaborative Multi-Agent Teams in Enterprise Git Workflows
A complete practitioner's blueprint for deploying the Claude Coworker framework in enterprise repositories.
Anthropic Claude Code: Mastering the Agentic CLI for Headless Software Development
Master Anthropic's Claude Code CLI. Deep-dive tutorial on installation, secure environment permissions, scripting, and running headless agentic operations.
LLM Evaluation in Production: Agent Benchmarks That Actually Predict Failure
Stop relying on MMLU or static evals. Build a production agentic evaluation pipeline with golden sets, CI/CD regression testing, and real-time shadow
External Standards & Publications
Our engineering publications follow industry standards for software architecture and agentic AI systems. Read more about technical specifications at the IEEE Standards Association and general web engineering principles at the World Wide Web Consortium (W3C).
What is “LLM Evaluation in Production” about?
Stop relying on MMLU or static evals. Build a production agentic evaluation pipeline with golden sets, CI/CD regression testing, and real-time shadow.
Who wrote this article and when was it published?
Written by Vatsal Shah, an AI Leader and Solution Architect based in Ahmedabad, India, and published on June 28, 2026. Reading time is 20 min read. It is filed under AI / MLOps.
How can I apply this in my own organization?
Use the sections of this article as a working checklist, adapt each step to your platform and risk profile, and record the decisions you make. To discuss LLM Evaluation in Production for your team, request a briefing at https://shahvatsal.com/contact.